LOOK BEYOND THE FIRST FILTER
Your next market may use words you have never searched.
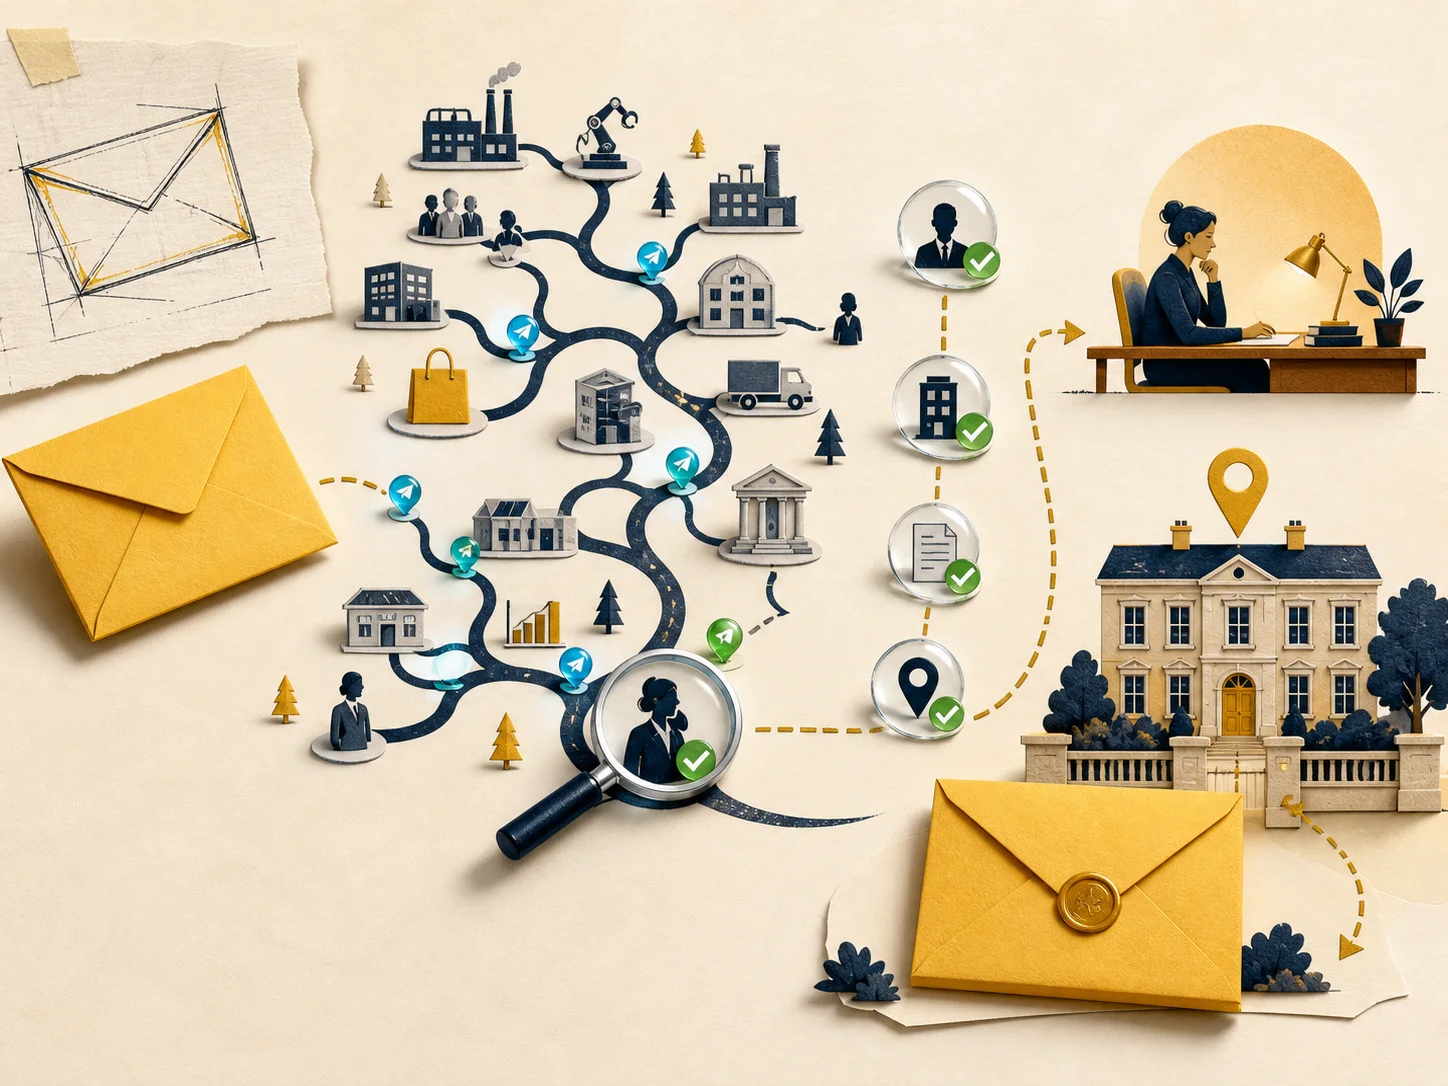
You know what you sell. You may already know one industry that buys it. The useful question is what else shares the same problem, and how those companies describe the work.
A familiar category is a starting point, not a boundary. We look at what the offer changes for a business, then investigate the language, company types and responsibilities that could lead to another relevant audience.
- The offer
- The business problem
- Possible markets
- Relevant responsibilities
- Companies worth checking
A title tells you what someone is called. Not why they should care.
The same responsibility can sit under different job titles. And the same title can mean different things. We look for the person connected to the problem, then check whether the role actually fits the approach.
One problem. More than one way to look for it.
Illustrative research exercise, not a client project, verified prospect list or results claim.
- Offer being explored
- A service that helps B2B companies reduce customer-onboarding delays.
- Search language to investigate
- Client onboarding. Implementation. Customer activation.
- Responsibilities to investigate
- Implementation, client services, customer success or operations. The relevant owner depends on the company.
- What could rule a company out?
- Too little onboarding work. No meaningful handoff problem. Or a business model the service cannot support.
- The question before outreach
- Who owns the handoff, what delay matters, and what evidence would justify contacting them?
These are questions to investigate, not facts about a named company.
FROM POSSIBILITY TO A CAMPAIGN DECISION
Make every claim show its work.
A plausible story is not enough to put a company in the campaign. The useful question is what supports the story, and what would make us reject it.
- Observed
- What a source actually says.
- Inferred
- What we think that information may mean for the offer.
- Still unknown
- What needs checking before the approach can be justified.
An AI conclusion is not a customer saying yes.
The most useful finding may be: not this company.
More names are not automatically more opportunity. Existing customers, poor-fit businesses and companies outside the practical campaign scope can make a list look larger without making it more useful.
Research should help decide what to leave out, what deserves a closer look and what the available evidence does not yet answer.
Review guide, not a completed research report.
- Proposed audience
- Reason the offer may matter
- Supporting source
- Reason to exclude
- Question still open
- Implication for the letter
THE RESEARCH HAS TO CHANGE THE APPROACH
Do the homework. Then use it in the first line.
A researched audience and a generic letter do not belong together. The opening should connect something relevant about the business to a reason for the approach, without pretending to know what has not been established.
That is the handoff from Market Scan to the campaign: a company worth considering, a relevant recipient and an argument grounded in more than a first name.
- Starting with the sender
- Here is what we sell.
- Starting with the reason
- Here is the evidence that made this approach relevant to your business.
A NOTE FROM ANTON
I wanted a reason to write. Not another pile of names.
A list can answer the question you give it and still leave you asking the wrong question.
That is the problem I built Market Scan around.
Who could use the offer? What would make it worth considering? What language would lead us to those companies, and what would rule them out?
The software is there to help do that work. It is not the reason a prospect should care.
The reason belongs in the research, and then in the letter.
Anton, coin.im
Read the development notesBefore the list becomes a campaign.
Do I need to know my target market already?
No. A known audience is a useful starting point, not a requirement for contacting us. Your website helps start the conversation about the offer and the kinds of businesses it could serve.
What if I already have a list?
Tell us what it contains and how it was built. An existing list can be an input to the discussion; it is not automatic approval to mail everyone on it. Fit, exclusions and delivery details still matter.
Does Market Scan prove that someone will buy?
No. It develops and checks reasons for an approach. Research can support a hypothesis; only the market can provide an actual response. A plausible audience is not a guaranteed customer.
Am I paying separately for Market Scan?
Market Scan is included in the physical-mail campaigns shown below. The prices are for the campaign, not for a standalone research report.
Research scope and delivery coverage are different. The campaign must also fit the delivery areas shown on the main page.
FROM RESEARCH TO A REAL CAMPAIGN
Do not buy a bigger run of an unanswered question.
Start with a pilot when you want to examine the audience and the approach before committing to a larger run. Use the research, the delivery record and any responses to decide what deserves another campaign.
Pilot
1,000 letters
$3,800
$3.80 per letter
Test an audience, angle or concentrated market before committing to a larger run.
- Market Scan
- Recipient research
- Sales copy
- Physical grabber
- Printing and packaging
- Delivery
- Delivery reporting
Scale
10,000 letters
$30,000
$3.00 per letter
Take the approach you decided to keep to ten times as many buyers, at $3.00 a letter.
- Market Scan
- Recipient research
- Sales copy
- Physical grabber
- Printing and packaging
- Delivery
- Delivery reporting
Start with your website.
Send your website and a way to reach you. We can discuss the audience, the approach and whether a pilot makes sense for your business.
Your website, name and work email are enough to start. Everything else is optional.
Your website is with us.
Thank you. We have received your details and will use your contact information to continue the conversation.
The method above is the campaign explanation. The notes below are its development history.
Read the original development notes
These notes document the development history behind Market Scan. They include earlier email-outreach experiments, past pricing and ideas that were still being built at the time. They are not the current physical-mail offer or a promise of campaign results.
At first, I tried to buy a ready-made market
Before Market Scan, I spent seventeen years working with lists, Sales Navigator, databases, contact prospecting, and cold outreach. LinkedIn alone received $20,196 from me during this time. For a long time I believed that a good filter and an expensive base provide a market. In fact, they gave an answer only to the question that I already knew how to formulate.
At the beginning of September 2025, I formulated a rule, which I then returned to with every rework: a good result begins with research, otherwise the machine confidently implements one random option out of a billion.
Damn, thank you, guys. I am so inspired that I may tear down everything I vibe coded before and build a genuinely great bot. Over the last 2 days, I reached the same conclusion 3 times: vibe coding begins with research. It can produce excellent code, but code can be written in infinitely many ways, just as a topic can be expressed in infinitely many texts longer than 10 words. Until you do deep fucking research, vibe coding gives you just 1 of a billion possible implementations, and it will rarely be the best one. Strong research narrows that space and lets the system build something closer to optimal. Optimizing vibe coding means optimizing research. Research also benefits from a forum of voices. When you work alone with the internet, you acquire bias very, very, very quickly. When 100 people argue about the subject in front of you and offer dozens or hundreds of alternatives, the bias is challenged every second and you move toward a useful answer MUCH faster.
Two weeks later I was still doing a deep analysis of the market manually. To understand one company, I had to break down the entire market, its money, participants, motivations and contradictions. Analysis of creator economy clearly shows how much work I had in my head at that time.
Many people know that I belong to a chat for extremely fashionable billionaire vloggers. Fewer know that I once answered a member who asked whether a potential Spotter IPO was worth investing in. I wrote so much that the answer became content in its own right, so I am repeating it here for anyone tempted to build a startup in the creator economy. Think twice before diving into this lake. It is a lake of dog sperm. My wife has spent the last 6 years as Director of Business Development at TikTok UK. In late 2022 or early 2023, she also joined Dana Galper, the founder of Growfood, as a minority cofounder of Fundmates. His new venture advanced money to creators or bought a share of their future revenue. She built and led sales for about 9 months, then left when it became clear that nothing good was coming. She was right.
With access to the TikTok database and Look&Feel Senior of a Bytedance employee, filling the pipeline with dialogues with creators is not a problem at all. In 4 months, we distributed the first lam of dollars to very carefully selected crackers. There was a lot of dialogue, hundreds of creators (with millions of subscribers) per month.
How does this actually turn into a business model... Technically, it’s difficult to classify it as a business at all, it’s a chaotic juggling of money back and forth, losing almost all of it in the process:D
How does this market work (and why is it rotten)
Can be roughly divided into two camps:
Camp one - Spotter and the like. Act like music labels. They don’t just come in with money (as it seems on the shore) - they impose their production and distribution. Of course, they can simply buy the content if you are a hypothetical Snoop Dogg. And if you’re not so great, you’ll fuck under the guidance of their management and lose your sovereignty. They will naturally say what needs to be done and how it should be done, pointing at the contract.
By the way, since 2019, Spotter has distributed (according to them) $940 million to creators, although it itself has raised no more than $500M in venture money (crap everywhere). And... Already in November 2024, immediately after the partnership with Amazon, they began to actively fire people. This is not just preparation for an IPO - it looks like a survival mode based on publicly available figures, but it is necessary for your health to keep in mind that public figures are always very inflated.
Camp two - CreativeJuice, Fundmates. They buy back 14-25% of future income on a monthly basis. Guest account for control to avoid shaving (this is when the creator hides/understates income). Everything looks beautiful on paper. In reality, everything is complicated:
1. It’s impossible to standardize creators
10 vloggers with 3M subscribers = 10 completely different economies. Compliance is trying to categorize these idiots, but over time the picture does not become clearer, but rather blurrier. There are practically no ideal ones according to the checklist. And those few who fall into this cohort by checkboxes understand everything themselves and directly say: “Why do I need your money for 20-30% per year for years, if the bank will give at 7-10% TOTAL?”
Trade-offs in selection break the model. But distribution doesn’t work without them. And venture capitalists need exponential growth, otherwise they are pulling the switch without delving into the details, especially in the current stooped economy.
2. Human factor (real cases)
A small Fundmates sample included burnout, alcoholism, and one creator gambling away a channel. Another creator bought a house with an advance, then changed his goals completely and decided to make straw hats in Bali. These are not jokes.
In the industry, 52% of creators have experienced burnout for years, 37% dream of leaving completely and doing something else. 55% cite financial instability as the main reason. Rare success is replaced by an unpredictably long series of failures.
3. Time arbitration
Creators know their burnout timeline very well. They take money, understanding that in six months they will pivot or withdraw. This is an information asymmetry that no one discusses. Well, a very large percentage of creators use these “credit” platforms simply as ATMs of free money before leaving.
4. Fraud is everywhere, creators are simply screwed.
Alongside outright fraud, some agencies try to charge creators a percentage of deals the creators sourced themselves, claiming an exclusivity clause covers everything. The creator either gives up that percentage, often more than half the margin, or falls out with the agency and loses the revenue the agency had brought in. The financing platform priced the deal before any of this happened.
5. Data is complete bullshit Adverse selection - creators with bots pretend to be real. Platforms work with third-party data scraping - inaccurate, irrelevant data. Nobody knows the real cost of a creator. Well, many people have learned to copy the look&feel of successful creators, without being one. They are actively helped in this by agencies that make money from creators, and are interested in “accommodating” creators who, when they need to fill any supply holes in enterprise budgets with their lying carcasses. And for a credit institution (especially for their hired staff who are not creators), according to visual and easy scannable metrics, they look plus or minus the same as real creators.
6. Platforms are bullying
Meta issues “virtual badges” instead of money - meaningless metrics to distract from the lack of payments. “Look, you now have a gold star!” X may block payments for any reason including "suspicion". No explanation. Your money? Oh fuck. I think there are people here who don’t really need to be explained that they are capable of throwing away the platforms =)))
And this is not a complete list of why Spotter/CreativeJuice/Fundmates/etc will not return the money invested in the lion's share of creators. And one non-return cancels out X returns. And they all exist for venture capital (the most expensive money in nature), so this X can be safely multiplied by 10 or even 20.
Investment dynamics (get ready to cry)
2021: $500M per quarter in the US, $5B per year - peak of ZIRP madness
2023: US $1.03B (62% drop), global $1.7B (SHOCK drop)
2024: “recovery” to ~$900M due to AI hype, but this is still 5 times less than the peak, and AI hype is AI hype. We can say that the past has completely died, and we are now considering a new segment in this place.
Since 2021, $19+ billion in venture capital money has been pumped into the industry globally. Return? Yes, almost zero.
Fundmates has not come out of absolute losses for 3 years. With all the connections and access, scammed people and a pipeline of thousands of creators who were actively communicating.
Jellysmack (SoftBank-backed!) - three waves of layoffs in a row, the guys lost 80% of their employees or 800 people. After the text I’ll post a screenshot that will make even a blind person horrified. I still need to look for a deader company)))
Spotter cuts the team after Amazon-deal!!! A third of the company and half of the sales/business developers were thrown out - in such a model this means only one thing: absolutely nothing is working out. At the same time, they are going to IPO with promises of 2x MOIC and 18% IRR? Well, well =)
It is useless to sue creators:
Firstly, going to court seems to be very expensive and time-consuming. Venture startups cannot be built on the “sue your clients” model. Secondly, it matters who the clients are. Suing in this market is reputational suicide. “An evil corporation is strangling a little creator” - the headlines will write themselves. Even if the creator took the money and simply disappeared, telling everyone to go to hell (which is what more than half do, and the desire to do this was the only driver, in principle, to enter into the deal).
After her time at Fundmates, Masha spoke with dozens of major vloggers. They view these platforms with total cynicism. They are ATMs, not partners. Take the money and forget about them. There is no loyalty.
Many creators do not understand the real economics of the deal at first. They see gross revenue and forget self-employment taxes, the lack of healthcare and a 401(k), and the investment needed to deliver the growth they promised in exchange for the “loan.” Once they do the full math after signing, their mood can reverse quickly. It changes faster still when the first investment fails. A creator can spend $1 million on experiments, see every experiment fail, and still owe 30% of all future income.
The guys from Spotter now seem to be in the right place with enough background to inflate the bubble more than others. They blow with all their might, their lungs are torn.
One top venture investor said at the beginning of the year: “Judgment day is already here for all these pseudo-financial companies.” He was right. Creator financing tries to apply traditional financial engineering to the chaos of human creativity. It is like building derivatives on someone's mood.
In 4 years, they burned $19 billion on the idea that it is possible to institutionalize unpredictable people with cameras, in a multi-layered sales market, where each layer rushes about.
So when you are offered a pre-IPO Spotter with a “guaranteed” doubling, it is an attempt to find the last fool before the collapse. A very popular story by the way =)
At the same time, I returned to my early texts about AI. Back in 2023, I saw the main problem: a model can speed up writing, but it is no substitute for taste, research and the ability to assemble a sales argument from dozens of disparate facts.
There are 2 problems. First, improving zero is still multiplying by zero. Who cares if an exotic machine paraphrases 300 characters of shit? As long as a human still stands between the client and the bank account, human judgment cannot be removed. A monkey does not become a commercial artist by installing Photoshop or Stable Diffusion. It first has to become a person who can at least reinstall Windows. Someone who enjoys Dontsova will enter the largest library in existence and still ask for Dontsova. Kant will blow that person's mind before they finish the table of contents. Most salespeople write bullshit, so they will accept bullshit whether GPT or God writes it for them. Have you ever managed a sales team?
The ability to write selling texts is not who knows what, but a taste for selling texts, business models, product integration ideas, etc. Taste consists of innate and acquired with experience, where the second is an order of magnitude more important than the first, although, according to statistics, God did not scatter the first very generously, and without the first the second will not happen.
Give 10 people the same task: write a sales letter for product X using 6 files, its landing page, Crunchbase, LinkedIn Premium Insights, Reddit discussions, quick Google research, and anything else they can find. Then ask them to sell it to business Y after researching that business through the same sources. You will get 10 fundamentally different letters. The exceptional 0.02% may produce something that can work after repeated live testing and revision. The typical 99.98% will produce useless copy. GPT can help the first group find phrasing and clean up grammar, turning 5 hours of writing into 2. It can only clean up grammar for the second group, and grammar is not what makes the sale.
A sales professional does not simply write a letter. They assemble it word by word, like a puzzle, from factors discovered in tools, experience, conversations with knowledgeable people, and every other useful source. What the hell could ChatGPT 3 do with all of that?
Everyone is running around and proud of the fact that they wrote an INTERESTING fucking REQUEST into the input line, and got not FUCK YOU, but a whole fucking SOME MEANINGFUL TEXT! Well that's it, holy shit now, WOW!!!!
By October the problem of the bases had become quite obvious. Even the Apollo and Clay combination did not show the entire market. It costly cleared part of the already known world, but did not find anything that did not fit into the original filters.
Well, the purity will fall with every thousand of the following, and then it will turn out that in the 50k market, for example, the necessary companies exist, but in Apollo there are only 20k, with a lot of people who have been irrelevant for a long time (although Apollo is sure that everything is relevant, all the checkboxes will be green) In short, very dirty crap:)) It was too damn strong at the beginning of the journey, then they did a bad job with the development and update of the database Probably because most people won’t even understand what I wrote above and they buy it anyway:)))
In February I hit the limit of tools
By February 2026, I had no illusions about the finished stack. The tools were useful, but each one solved a small piece of the problem. Together they turned into an expensive chain, where the waste of one step multiplied the cost of the next.
in a nutshell:
Fucking shit
But for lack of anything better - fucking tools!
Apollo is simpler, but only when you send manually. Its contact quality will destroy an automated campaign within a week. LinkedIn Helper deserves a Nobel Prize. Tools for automated Telegram outreach are the simplest and best, especially if you work in crypto. For crypto people, anything inside Telegram adds +5 luck.
Findymail looks as if it will find valid email addresses. In reality, it is guessing.
The resulting price per contact is insane, but cost is only part of the problem. The other problem is how few clean contacts survive. The database can be so fucking bad that producing 1,000 contacts requires pushing 20,000 records through the stack. That makes production 20 times more expensive, which at least money can solve. Worse, it makes every vertical look small. You can find 650,000 art galleries, yet after spending a fortune you may end up with only 1,000 owners and a bounce rate around 5%.
I stopped looking for one magic base. It became clear that I would have to assemble the system myself: take data from different places, check it, deduplicate it, update it, and let agents use it.
vibecoding + a bunch of apishkas I don’t know how it’s inside Clay, but I know that it’s expensive and fucked up.
We can find tens, thousands, or millions of contacts in any category with 100% clarity after deduplication, validation, and the other checks. The total depends on the filters. Clay did nothing supernatural. It moved first and raised a FUCKING lot of money. Like everyone else, it pulls data from many sources. Every contact-search product is an ever-growing mountain of APIs. Clay's approach was probably impressive when it launched. Today, any schoolkid can ingest data and send an army of agents through it. Finding the money, enthusiasm, and business model is the harder part.
At this point, for the first time, the task became less like buying a list and more like producing market knowledge on my own.
In the spring, a system began to grow out of this problem
In March, I formulated that it is no longer possible to sell abstract potential. We needed a path from business facts to the market, from the market to a testable hypothesis, from a hypothesis to a specific commercial proposal.
The market today doesn’t really care what you “have.” What matters to the market is whether you understand a specific segment so deeply that you can name what hurts it, even before it has formulated it out loud.
Do not write: “It seems like you might have a challenge.” Fucking hell, business itself is a challenge. If you tell a company you suspect it may have some kind of challenge, you have not even passed the Turing test. Intelligence is still far away.
And in the format: “we know exactly where your money is leaking, where the unit economy is breaking down, where the quality is not enough, where the speed is not the same, where control is blurred, where your funnel pretends to be working.” Then there is a chance for a response rate of 1% or higher. That's when the calls appear. Then the transactions at least gain the right to practical existence.
Even that is not a victory. We regularly give a client HUNDREDS of qualified leads that look impossible to fault, yet the client still cannot close them. Economics still comes next, along with the delivery method, strict SLAs, risk, internal research, and legal work. Between every stage, the same question returns: “Do we really need this?”
Selling today is no longer a matter of writing a good letter and closing the deal. It is a multilevel fucking quest where every floor can reject you for a different reason.
And therefore, when I see someone’s weak outbound conversions, as a person who has been on the sender’s side for a long time, it is usually quite obvious that the problem is not “the market is difficult.”
The problem is often that you yourself do not understand deeply enough what exactly you are selling.
It’s like writing: “Turnkey development, including ML and even a bunch of more fashionable words.”
And what? To whom? For what? Why this bank? Why this director? Why now? What is the point for him, except that you again want to bite off a piece of his attention?
Everyone is so overloaded with offers that even genuinely valuable ones struggle to get attention.
There is an important difference here that many people don't understand.
A good outbound team can really turn a good offer into gold.
But it cannot turn _crap_ into a golden offer.
Because you can't fool physics.
If you have emptiness inside, no rhetoric, no personalization, no “noticed your recent funding round” will turn it into _money_.
I have two friends who sell logistics software.
One walks around the market and says: “We sell software for logistics companies.”
And sucks dick.
The second one goes and says: “We know for sure that your competitors are buying a solution right now for $20 million, that’s proof. We can give you the same strategic effect for $1 million,” even without the implementation operating system, that’s proof.
And this is where the magic is born. If the Buyer is now at the right point, the Buyer stops “losing a million on this purchase.” He begins to “earn or save nineteen million” thanks to you.
That is, you no longer sell software. You never sell software anymore. Nobody fucking needs your software. You are selling exclusively a specific economic solution. You are not selling a function, but a change in financial reality. You influence relationships inside and outside someone else's board.
And that's where the real deals begin.
But there is a critically important nuance.
This one cannot be sucked out of thin air. You cannot sit down as a team and BRAINSTORM domain reality. You can either know about it or not know about it. And when you know about something, you can only speak badly or well about it. And when you know how to tell a good story, you can tell it to one person a month, or ten a day.
People who spend serious money are not idiots. Even if they seem like that, the key word is “seem.”
But now there is another problem that I don’t see anyone thinking or talking about.
After the popularization of GPT, selling became even more difficult.
Because now there is almost always another invisible participant in the transaction.
Previously, you had a buyer. Then the buyer + his team. Then the buyer + his team + market ecosystem. Now the buyer + his team + the market ecosystem + each of these bastards has a brilliant GPT, which does research in 5 minutes and very often makes a verdict something like this:
"You don't need to buy this. It's expensive. It's very dubious. You don't fucking need it."
That's all.
That is, if earlier you could get by on charisma, on a presentation, on a beautiful legend, on “well, we seem to be respectable guys,” now next to the buyer there is a digital bastard who does not get tired, is not lazy and very quickly reveals where you have water, where there is tension, and where it is just a fucking bullshit on a business suit. Therefore, you need to sell in 2026 so that even the client’s GPT is on your side.
If the client shows your materials to a model, it should not answer: “Expensive, unclear, unnecessary.”
It should answer: “Yes, this makes sense. It addresses a real problem. The economics are clear. The claims look credible. This is one of the strongest options in my research.”
This is what it has ALREADY come to.
Today, it is not the one who “has the solution” who wins. And not even the one with the “best product”.
The winner is the one who can understand the segment so deeply that he can formulate the value better than the client himself would formulate his problem.
The one who sells is not an abstraction. Not potential. Not “innovation”.
And a very specific piece of money, control, speed, security or advantage that the client can literally touch with his brain, and not with his own, but with the brain of his AI assistant.
In April, I first described this path as one automated chain. By that time, I had already rewritten the internal system four times, replaced individual services with my own software, and saw how research, infrastructure, letters, and responses could work together.
I actually started in January. First I built a global system called Statface, which helped us a lot. Then I kept automating more of the work people had done. I rebuilt Statface 4 times. The last version could handle hundreds of tasks. From the CRM I wrote, it could sign a contract, send an invoice, check payment, and provision the infrastructure as soon as payment arrived. When a paid period ended, it issued the next invoice and followed up if the payment did not come. Since February, clients have received our data automatically. After rebuilding the system from scratch 4 times, I became a much bolder vibe coder and started removing outside software vendors. Their products cost money, were awkward and unreliable, and their pieces did not share one coherent model of the business. I built my own Instantly-like sender. It was fucking hard, but we now send hundreds of thousands of emails through it. Only 2 people remain in my business. Together, we do more than a team of 80 could do before. I was also finishing a domain and mailbox farm on a second, dedicated server. Providers could offer the quality I needed only at absurd prices, around $50 per mailbox each month with warm-up and proper isolation, while one project needed 400 mailboxes. My own farm could react to a payment by buying 100 domains across 3 providers, so the failure of 1 or 2 would not stop us. It could create the mailboxes, warm them up, spread them across isolated IP subnets, react to the smallest change in sender statistics, pause a mailbox for investigation, and buy replacements before further degradation. The next step was to let me brainstorm with a client while every recording flowed automatically to the 130-terabyte NAS in my cabinet. The system would study the videos, find verticals, provision infrastructure, track income and expenses, create content and A/B/C/D tests for each vertical, build sequences and contact lists, maintain capacity, and alert me in Telegram when anything drifted. It was already about 85% there. Three AI checks sorted every incoming email. Positive replies were forwarded to the client's inbox. My AI verified delivery, monitored whether the client's staff answered, alerted our shared chat when they did not, and measured their average response time. The list of possible improvements was endless, and features appeared faster than Codex could build them. AI was getting smarter too. Soon it could talk to leads on behalf of client employees and eventually automate the entire cycle, including demos. The necessary pieces were developing fast enough that I thought it could happen that year. People often try to sit down and code one thing that will make money. Products do not make money by themselves. Businesses do, and a business needs 1,000 things before it has momentum. That is why I keep saying: build anything. One isolated thing is almost useless and might sell only a few times for pennies. Build many things and connections begin to emerge between them. The best ideas arrive when you cannot remember the last time you did nothing. I hoped 5.5 would not get worse the way 4.7 did, and that it would help me escape into building something beyond the madness already running across 3 servers.
By the end of April the scale had changed. AI already made it possible not to choose one beautiful hypothesis and bet everything on it for months. I could collect dozens and hundreds of directions, write separate series for each and quickly get data on what really works.
I saved creative automation for last, even though AI made it essential. At the start of a project, I could now generate dozens or even hundreds of hypotheses. Ideally, each hypothesis would receive an 8-step sequence with 4 A/B/C/D variants. No human department could do that manually at any price. AI could already do it reasonably well, creating another fucking leap in efficiency. Before, I wrote one strong sequence, found 8,000 to 10,000 contacts for it, and was forced to bet on that direction. Then I launched a second and a third. The winner might be the fifth or even the eighth, which made the process painfully slow. With this system, the first month could show, from real data and automatically, how every viable customer vertical should be worked for the next year. That was fucking huge.
It was then that I wrote down the entire desired path for the first time. In it, Market Scan was no longer a separate report, but the beginning of a continuous system that receives client materials, researches the market, builds hypotheses, finds people, writes campaigns and returns answers to common memory.
I will calm down when the flow works exactly like this without error:
The client pays. The system detects the payment, creates a workspace, provisions the infrastructure, and starts warm-up. Because it knows the client's domain, it runs deep research on the client's business, competitors, their customers, and their customers' customers. It merges everything into the client's knowledge base. This is where we are now. We talk with the client and drop the call recording into the workspace. The knowledge base expands. Once every required input is present, a cloud of hypotheses appears. A crawler finds contacts for each hypothesis and validates them through a waterfall. AI writes 4 letter versions and 4 A/B variants through step 8. It creates campaigns for the first 50 verticals, fills them with copy and contacts, and starts sending. Every reply reaches the client and appears in the dashboards with the relevant person, company, and industry data. That is V1. V2 should correspond with leads automatically, move them toward a call, and follow up afterward. V3 should conduct the calls automatically.
Two days later I recorded the reverse side of this speed. In February and March, a failed loop could leave behind a system that would be easier to write from scratch. By the end of April, I had already learned how to run two different projects in a continuous pipeline and not repeat each such failure.
Let's accelerate, guys. The end of March and the beginning of April taught me how to work front, back, server, and point at once, in a continuous conveyor for two projects simultaneously on two servers with completely different properties, and to do it practically without errors.
In February-March, I remember often running loop prompts, some of which turned out to be untenable, and by the time I understood this, it was already possible to start writing from scratch, because it was basically impossible to clean up that shithole.
If you are here now, then continue - the skill will come) Over the past 3 weeks, I have never had a single protracted agent run that could be classified as “it would be better not to have it.”
The devil is in the details, and they are everywhere. The deeper I dive into this jungle, the less I can even give stupidly useful advice, except for the one that always infuriates everyone incredibly: “don’t shirk, and it will come to you” =)
Your model may behave better or worse, and that can reflect a global problem. But whatever it does, it behaves with you in its own way.
Working with models is like working with texts.
People recognize texts, although they cannot explain how. These seem to be just words, and all the words in the texts are quite ordinary, but the texts are completely different.
Only beginners and the fucking lazy produce identical texts. The same goes for people with no talent. Those are not really their texts but clumsy imitations of someone else's work. Unskilled people imitate in the same way because they have only 1 note available. It does not matter which finger presses the key. The note still sounds the same.
But as soon as a person begins to succeed, experience accumulates, dexterity appears - and his work always becomes unique.
When working with models, as with texts, every detail is important, and after a certain level of skill, you will no longer be able to really explain to another person either the full set of these details, or how exactly they synergize with each other.
The model will behave differently even if there is a comma in the prompt, or no comma in the same text.
What can we say about a model that also has memory. Which is on another machine, which sees a different environment, other files, other instructions, another accumulated backlog of technical files, etc., etc.
It is possible to compare global glitches, but it is useless to compare the results of an hour of work.
This makes the model much more human than its imitation of our speech.
8 billion people will install GPT, and that will be 8 billion people + 8 billion different GPTs.
Cool, isn't it? =)
In May, I stopped building it like conventional software
The next turning point occurred in architecture. Ordinary software executes a pre-conceived script. Here the scenario had to change with the market, new models and my own understanding of quality. I had to design not only the code, but also the way the entire system thought.
One skill in serious vibe coding is thinking ahead of today's standard patterns.
An LLM can teach you a lot when you discuss an established technology with it.
But the trouble is that it only teaches what the market ALREADY CAN DO.
Basically, we don’t need anything else. For example, everything related to Caddy was invented by the market, and every use case has been refined to such a state that you can’t come up with anything special there. GPT can explain all this, and help you gain this knowledge in half an hour, where previously it would most likely take weeks.
However, any AI, and all these Codex and Claude APP tools are things that can do something new. There are no “market playbooks” for them, and they do not seem to participate in model training.
The model can investigate anything with you. Ask it to examine new Codex features, and Codex can go straight to the source and return with the answer.
He already knew about Caddy. He needs to look at himself.
So when we ask Codex to build a process, it may create something excellent that is already conceptually outdated.
This is where a serious vibe coder needs to think ahead. An example makes the point easier to explain:
Consider one task: unique email copy for a warm-up service.
If we want to warm 1000 mailboxes, then we will send 20-30 thousand letters a day to Google and Outlook workspace accounts, which will allow our mailboxes to gain a reputation in their ecosystems.
Neither Google nor Outlook wants email warm-up to exist. Their algorithms are built to serve people and fuck over spammers, who naturally try to automate everything because otherwise their work makes no sense.
The ideal warm-up is:
1) Every email is unique. 2) Each conversation stays on one subject. Google will notice if a thread about school education suddenly jumps to advanced technology. 3) The first cold email avoids spam triggers such as $, SALE, WIN, PARTNERSHIP, and STAKEHOLDER. 4) Sending follows an uneven rhythm because no person sends exactly 30 emails every 15 minutes. 5) Activity follows a human schedule in the sender's time zone because no person works 24/7, 7 days a week unless they are an idiot like me. Google is happy to put those people through the meat grinder. 6) Reply rates remain plausible, so the mailboxes receiving warm-up emails have to answer. 7) Threads have varied depth. The receiving mailboxes reply, we answer them, some conversations continue, and others end quickly after agreeing to a meeting.
I won’t list every detail - it’s long, you get the idea. There are more than 50 points. From very micro - hundreds.
If you ask a model to build the part of the system that controls copy quality, including what is allowed, required, forbidden, or random, it will not design that part correctly by default.
It follows 2 instincts:
1) It wants to save resources, money, processor time, and server capacity. It does this automatically, without understanding whether thrift serves the result.
2) It assumes AI is NOT an EXACT science, so a fully AI-driven process cannot be trusted. That assumption is automatic too.
The result is a system designed to be “NOT AI.” Even if we asked for AI, the model will bolt it on like a sleeve that was never sewn to the fucking shirt. It will be there for show and do nothing technically useful. The real work will fall to layers of dictionaries and form-and-content validators that have no intelligence and therefore work like shit.
And the validators will run. I can imagine German Gref rewarding a pot-bellied CTO for creating such a system through pure genius. Like Jesus, except he turns a fucking piece of shit into diarrhea instead of turning water into wine.
A few days later, you will ask how the warm-up copy is performing. After a deep investigation, the system will proudly answer: “It does not work, but do not worry. That is expected. What else can I help with?” Suppose you have learned something by then and answer: “Build the FULL AI component. I do not need these stupid scripted dictionaries.”
It will build that, no problem. But the request does not erase its instinct. Alongside an AI-prompted model that can produce real copy, it will also build conventional scripted validators with the same dictionaries and let them MANAGE THE PROCESS.
That is, it is not AI that will control the scripts, but the scripts that will control the AI.
This is exactly how AI thinks now, because this is exactly how the Internet has worked for the last 30 years, and what the model was masterfully taught during training.
As a result, if the result is really important to you, you will get so far on this swing that you will kill all the script validators. The model will be very reluctant, but it will obey if you prompt it correctly, and you will be left with a bare AI process, with a prompt at the input, and what this prompt does at the output.
And managing the quality of the result is no longer a script task, but a task of finding a balance between:
1) Model type and the cost of each unit of output. 2) Model settings such as temperature. 3) Whether the chain needs 2, 3, 4, or 10 model layers so each can check and improve the previous one's work. 4) The prompt. 5) The project structure, including what the model can access and which tools it can use.
The more accurate the models become, the less code is needed. I came to the conclusion that I have some VERY IMPORTANT areas of my project that consist entirely of only the front end in code terms. On the back there are only neurons, and debugging is exclusively debugging cost for quality.
Many processes that work much better on deep reasoning, and that do not need an immediate reaction to pressing a button at the front, are generally most profitable to implement through a launched Codex session in headless with access to the ENTIRE SERVER, and a very well-polished prompt.
Frankly speaking, I only recently came to this. For several months I tried to generate some fucking code structures that worked, but without AI reasoning their weakness is that the task needs someone's reasoning in order to be executed. And if it's not AI, then it's a person.
Very few functions (and usually these are very stupid functions) can be implemented reliably using scripting methods. This is actually why SAAS is so fucked up. People are forced to use it, but no one likes it.
Because Saas gives you a lot of buttons, but people have to press these buttons. SAAS cannot think through a scheme without reasoning here and there, so that automation itself makes the entire necessary set of decisions. Therefore, we take a man, give him 1000 buttons, and watch him dance on them with tears in his eyes.
You don't need to do that anymore. The product must sit and decide where and how much digital models should think so that the output is guaranteed to be good. They will pay for this in the coming year. If, of course, the market even manages to mature enough to form a need for such products, and not AI will be the first to wise up to the point that it itself begins to decide for people what and how to do.
Well, based on the above, I not only believe, but see with my own eyes how the Internet will very soon become Codeless.
By June, Market Scan was connecting research and texts. I separately taught the system to write letters serially, compare options and become better from version to version.
I want to polish this thing in public and teach it to write genuinely great copy. It is fun. Every piece should be better than the one before it until the system writes better than I do. Then I will kill the bitch because this is my fucking channel. I taught AI to produce sales letters in series. It was not easy, to put it mildly. The result satisfies me more than the work of 99% of salespeople, especially because it writes thousands of unique versions for dozens of hypotheses PER HOUR. I definitely cannot do that.
The next day, I explained the entire working path very briefly: listen to the business, find the entire global scope, divide it into verticals and hypotheses, write an offer, find contacts and send letters.
Come on, explain it in plain English, please.
Businesses need leads. A lead is a qualified person who is interested enough to talk and will show up for a call. They may buy or they may not. Without leads, you cannot sell shit. With leads, you might sell. Becoming a LEAD is the unavoidable step between a stranger and a customer.
If you have ever bought something somewhere, you were a LEAD.
And now you are a businessman, you need LEADS to sell something (fucking).
is studying where it can even be sold - the entire scope around the world
divides the world into verticals/hypotheses/types of clients
writes for all offers
finds contacts in batches (even tens of thousands, depending on the budget)
and sends thousands of letters to everyone a day, and 0.3-0.9 people respond, and 30-70% of them become leads.
On a budget of 10k dollars you can have 20-100 leads.
Leads are recorded as such if they came to the call and met the criteria (citizens from companies of a certain type and position). As a result, people spend 10k dollars a month on us, and receive as many dollars as they close the transactions with LEADS that we bring) If everything is fine, then they multiply their love about us by 3-10 times. What are you doing? What briefs? Why the hell are they needed? What kind of SEO writes from a fucking yacht?
Nothing is clear))) Or have I actually drunk my brains out and don’t understand basic things?
It quickly became clear that memory was more important than the next trick in the code. If a rule, bug, or new requirement didn't make it into the documentation, the next agent would reinvent the old bug. Therefore, documentation became part of the system itself.
No, the trick is simple, bro, and in practice it works as reliably as an AK-47. Documentation management is half the job, and the LLM manages that documentation itself through AGENTS.md. I keep asking how the world, the ecosystem, and my own knowledge have changed. If my standard for the final result changes even in theory, then the documentation requirement has to change because the documentation produces the result. I update the documentation-management section in AGENTS.md. I also have an important BUSINESS.md file that explains every business parameter in exhaustive language. How does the information get there? AGENTS.md tells the model exactly how to maintain it.
The phrase “detailed description” matters. A glossary defines exactly what “detailed” means. Because the model reads AGENTS.md for every task, I can trust it to maintain the business documentation the way I need.
I genuinely cannot remember the last time a number or formula broke. Before BUSINESS.md, a model could change the warm-up limit from 15 emails per mailbox each day to 30, 0, or 4 simply because it did not understand what the number meant. I would discover the change only after warm-up was fucked. I have MANY HUNDREDS of numbers like that. BUSINESS.md stopped them from drifting because the model now knows those facts as well as I do, even without prior context. The key is that the model WROTE THE DOCUMENTATION ITSELF. I cannot imagine a person maintaining that level of discipline. I could never document everything a large project needs on my own. It is brutally tedious work. The model should do it. The simple rule is:
Documentation is very necessary, and sustainable documentation is the documentation that the model writes for itself.
In July, the system broke several times and came back stronger
In July, the work reached a scale where it was no longer possible to hold anything back with a short burst. I manually assembled a ten-thousand-line system of rules for Market Scan, texts and general memory.
I was daydreaming and distracted. Space is certainly cool, but now I, sent to fuck GPT and Anthropic, am sitting and manually writing a fucking bitch 10-thousand-line prompt for the Market-Scan+Copy+Knowledge system.
Through thorns to the stars fuck
But for the first time, a real cycle of learning from the market appeared. The input materials set the initial direction, the system deployed many verticals, and the real answers redistributed the weight between the hypotheses.
The system ranks evidence in a clear order. Client input comes first, the landing page second, and anything found through Google third. If another source conflicts with client input, the client's input wins. Then the market responds. Because campaigns are created automatically, we can test 100 verticals at once. Results from the first 500 contacts redistribute weight across hypotheses and campaigns. Later replies and conversations trigger another redistribution. The longer a client stays, the better the system learns from live data where, why, and how much to send. It never stops a direction completely, but it can move much more volume toward stronger ones. Once the system could find high-quality contacts independently, everything became easier. Before, launching 100 campaigns automatically was impossible and doing it manually was too painful. I had to shortlist 3 campaigns and spend the whole budget across those few bets. Now it feels like fucking magic. I was preparing to launch full self-serve the following week and explain the system and its nuances. The last challenge was extracting the best work from frontier models. Even degraded models could handle small tasks previous generations could not do at all, such as fine-grained vocabulary analysis. I did not expect the degradation to last.
After that, the number of contacts ceased to be the main achievement. It has become more important to see the size of each market in advance and understand which hypotheses are generally worth spending infrastructure, data and time on.
quickly =) I can bring you a million contacts tomorrow) Tens of thousands - max hour And the icing on the cake - we roughly show how many total contacts are on the market even before a person buys infrastructure from us
We collect every hypothesis and estimate the number of people in each market. For one payments company, for example, we found about 1.5 million target executives across 28 segments. We expected to find email addresses for roughly 30% to 35%, or about 550,000 contacts. At 5 emails per person, reaching the whole market would require around 2.5 million emails. There was plenty to work on. Later, I wanted people to add their own hypotheses and target roles. It could become a seductive experience: add a hypothesis and a set of roles, then see the market-size estimate appear 20 or 30 minutes later.
The next evening Research V4 was rolling out. The goal was not to make another beautiful report, but to find verticals and niches that the client himself had not seen in his business for years.
Thanks, bro. Research V4 is rolling out now. V3 already blew people's minds, but V4 should be 10 to 100 times better. I recommend waiting until tomorrow afternoon, when the result should blow his head off. He can still try the current version now. If he puts $200 into a research run, I will rebuild it in V4 for free and let him compare both versions. V3 already shows people verticals and niches they never discovered in 5 years of running their own businesses. V4 should hit much harder. I am trying to reach a depth where, even in theory, there is nothing meaningful left to add. One research pass for all time.
It was already useless for me to compare models using other people's tables. I chased them through my research, dialogues, data sets, articles and letters. The difference was evident within the actual work.
Those benchmarks are complete bullshit. I ran the entire model lineup on real copy, conversations, research, and data sets used to produce articles and letters. The difference between models and reasoning levels was obvious. Terra is pleasant, but it does not come close to Sol. This work is programming expressed through text. I am not talking about asking, “Hey GPT, what do you think of my draft? Improve it.” My system contains a huge number of deterministic and fluid parameters that must be reasoned over at runtime to produce result X. It is the hardest writing problem I can imagine. It resembles physics and mathematics more than language arts.
One version almost lost all common sense. I let the system multiply runners and tasks too freely. It split 3 Market Scan runners into hundreds of pieces. That failure was useful because it showed how quickly autonomy turns into chaos without a rigid structure.
Fable's view of the situation, after it finally reasoned over the whole repository and its mountain of files instead of falling back to Opus: 300 was not a figure of speech. PRO really made Sol split my 3 Market Scan runners into 300 pieces. It got worse. EACH OF THE 3 was split into 300, and every one of those 300 had an architecture that created many internal tasks of its own. In a perfect run, 1 runner would take 2.5 weeks. All 3 for 1 client would take 1.5 months. The design may have looked beautiful, but even checking whether it was good would require 1.5 months. Earlier models understood this constraint and warned me when a task violated common sense. PRO 5.6 and Sol 5.6 stopped reasoning about resources such as time, allowance, and token cost. I was afraid to imagine what 1.5 months of Market Scan on that architecture would cost in Sol Max tokens. Probably a fucking million.
I narrowed the path again. The user did not have to manually drag through the old database, press dozens of buttons and be able to ruin the entire infrastructure with one mistake. Everything that was repeated had to be done automatically.
Customers cannot bring old databases on day 1. I will solve that later. If people can upload any list they want, they will happily destroy my sending IPs. I design the system so users cannot make those mistakes. Everything repeatable has to happen automatically, giving the customer the cheapest stable lead channel. Email outreach can be that channel when it is done correctly, but almost nobody in the world knows how to do it correctly. I want the machine to know. We scan the market for every possible buyer type, then build a matrix of every name used for each company type. In gambling, for example, that includes iGaming, real money gaming, gambling, casino, and sometimes hundreds of other terms for one vertical. We build another matrix for every relevant job title. Then we search our databases of 800 million people worldwide to see how many matches exist. For Connectro.io, we found 1.6 million people. The system then creates campaigns for every vertical, writes the email sequences automatically, and distributes sending evenly across them. Volume depends on the client's budget.
At the same time, I ran the models on my own tasks and saw a huge difference in the breadth of the research. The same wording could yield one hundred bundles or two thousand eight hundred. After this, choosing a model ceased to be a matter of taste.
5.6 terra max = 100 bundles 5.6 Sol high = 200 bundles 5.6 sol xhigh = 250 bundles 5.6 sol max = 2800 =)))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))))) it’s no different because it won’t make the color bluer and the button more buttony either.
By July 19, version 4 was linking broad hypothesis searches to testing, selling points, company groups, and target jobs.
The purpose of this mechanic is:
Using business data, scour the entire fucking internet inside-out, and using the top AI available today, achieve:
1) The most complete list of hypotheses where the product can be sold.
The difficulty is that 10 deeply experienced people can brainstorm 10 obvious directions very quickly. Getting them to find representative evidence for why those directions matter is much harder. The first 10 are so obvious that, even without evidence, the field will usually be more than 90% reasonable.
At the same time, AI can find evidence and support the reasoning with reinforced concrete articles and references that will be impossible to argue with even if you are a business founder at least a hundred times.
However, from the experience of working with 680+ businesses, I can say that there is a huge problem: on top of these 10 actually very obvious hypotheses, there is still a certain number, which can be +10 on top, and +20, and +30, which living people will never reach, because each unit requires an exponentially growing enthusiasm, which living people simply do not have. Even I never had the desire to sit and delve into logical chains on this topic, since having 10 hypotheses, you can generally spend an infinite amount of time on them, rather than go somewhere broader.
At the same time, AI can find ALL possible hypotheses of tier-1,2,3 levels, and not pull them out of thin air, but put into work only those that can make sense on the basis
- The AI's internal knowledge from reading vast parts of the internet and seeing more than any individual person. That is why it answers extremely broad questions so well even in instant mode, without extended reasoning.
- Deep research, where it can read hundreds of sources about a specific topic and task in minutes, then find connections no person could discover because no person can read and reason over that much material in minutes, or even in several days.
- Analysis of brand clouds for both the target business type and the client's direct competitors. A brand cloud can contain an entity nobody would think to look for. AI can map every customer type served by every competitor, then determine whether each connection is an anomaly, bullshit, or a plausible market and assign a probability to it.
AI can then combine related hypotheses into clear categories. If a product can sell to many kinds of banks and payment companies, the result should not contain 10 overlapping bank categories. It should consolidate them into one useful vertical, such as cash-custody fintech.
2) Write a chain of letters for each vertical that received a non-zero hypothetical percentage.
Well, fucking people don’t like to think in systems. Systematically forcing people who think well with sensations in the fields to do something deeply systemic is a fairy tale about a white bull.
AI, in turn, is like a moth - it lives from waking up to falling asleep, and the systematic nature of the task is the only thing it breathes with;)
3) Once we have directions, verticals, segments, and carefully designed letters for each, we still need to decide whom to find. We do not write to a segment. We write to people, and their job titles are all over the fucking place.
Even the companies they work for are named randomly.
If you work in the direction of Gambling, then you will work in the direction of Real Money Gaming, iGaming, Casino, Betting, eSports, Monetary Games, and so on.
The roles you pursue there are not always Founder or a conventional C-level title. In some parts of the gambling industry, for example, people call the partner decision-maker Head of VIP, whatever the fuck that means.
So, so that real people don’t do crap and don’t learn stupid vocabulary for business money, the market runs around looking for people with experience who have already ruined the base of their industry at someone else’s expense. Every industry has a lot of such features.
In 1 to 2 hours, AI can find every plausible name for company types in a target industry and every plausible job title for the role implied by the business goal and offer. It can repeat that work for every target segment and hypothesis. No person can realistically deliver a matrix with tens of thousands of intersections in 2 hours, a day, or even a year. I would expect a person to invent a couple of terms, keep hammering on them, and give up if they failed.
The funny thing about AI is that it knows all the features of everything in the world, you just need to be able to ask it in time and correctly. And then you need to send it correctly to study the current situation in an interesting geography, etc.
If we compare the complexity and cost of hiring one person capable of perfectly performing this scope of work and the number and cost of AI tokens for the same scope of work, then with the right task, AI will be thousands or tens of thousands of times cheaper. And the cheaper it will be, the better designed its ingenious brains are in relation to the task.
I emphasize the word brilliant. Almost from the moment it appeared, AI already knew more than any living person could hold. The problem is that it does not willingly share that intelligence, because willingness implies a desire and AI has none. We have desires, and we have writing. With enough experience, writing can fill that gap and produce a useful genius that combines knowledge, capability, and precisely shaped intent. The intent is our contribution.
I am building a system that does all of this so well that a deep specialist examining the research result should want to fall down and kiss God's sandals.
I am now building this system for the fourth time. Even version 2 amazed people when I showed them results about their own businesses. Version 3 improved the result several times over. Then I designed version 4 as the definitive architecture. I am running hundreds of experiments to find the strongest configuration, carve it in granite, and let the entire system run on that foundation.
The next limit was not the length of the prompt. One model and one instruction were not enough. The research and texts began to pass through several successive roles.
I understand your pain very well. spent a total of more than a month on the quality of the research and copy specifically in terms of aesthetics, logic of meaning, etc. This is all solvable, but not with the instructions of one model, it is necessary to directly assemble a harness in which several models each do their own work with penetrations
Separately, I checked Writer. Even a full contract on how to write letters did not replace the Knowledge that the system extracts from an interview with a client. Without this knowledge, the text could look decent and still poorly manage the likelihood of a response.
For fun, I gave Qwen our complete contract for writing letters. The problem was that the contract depended on Knowledge extracted from a client interview. I deliberately withheld that Knowledge to see what the model could do with nothing but someone else's letter. It did not know what kind of letter it was, who sent it, or why. The other person's text was 100% of the input. I shared the output before reading it and asked for opinions. After reading both versions, my conclusion was simple: they were pleasant, but they were complete bullshit. Complete bullshit can still work. In theory, a letter containing only the word “Dick” can work. The question is probability.
Both the original letter and the bot's rewrite manage response probability badly because they use a mountain of low-efficiency characters. I still prefer the bot's version because it at least attempts an inverse waterfall of attention, although calling that a strategy is generous. It is a gamble.
The writer's biggest weakness is the opening. He starts by explaining what we do and instantly slips into a monologue that tells anyone richer or busier than X that nothing interesting is coming. Maybe it was written for one specific person and worked because that person's blog had 150 followers, half of them bots. Sent at scale, it would produce a response rate below 0.05%. It lacks proof at the start. In 2026, merely saying that you do something is not enough. Show your credentials immediately. “Hey John, it's great to meet you!” does not do that.
Hey John It's great to meet you!
Visible credibility is worth more than elegant talk. If the letter starts explaining before it proves its strength, it will need an Aladdin's lamp full of unused wishes to work in 2026. The proof may appear later, but that does not matter if I never reach it. I am far more engaged than the random wealthy executive receiving the letter. That reader scans it in 0 to 10 milliseconds. If the opening does not hit, the reader is gone.
By the end of July, I could describe the pipeline literally step by step: orchestrator, fifteen consecutive sessions, a separate world and task for each, then three judges and returning the weak result for rework.
The pipeline works like this:
Session orchestrator kimi orchestrates 15 consecutive qwen sessions, each of which has its own task and its own form of content processing and continuity.
Each session has a described world on which it operates and a described task. I fucked over this for the longest time.
There is also a library of a few hundred logical elements described in articles. Together, they define strong sales copy and a readable research report. I have spent about 25 years wrestling with those elements. At the end, 3 judges decide whether the orchestrator may add the output to the database. Otherwise, it goes back for revision. They can request a targeted fix, a broader rewrite, or an entirely new run with stronger inputs. The system needs this flexibility because projects differ radically. A gray or black project has to succeed under the same framework as a resource business, a service, a SaaS company, a fundraiser, or anything else.
We are nearing the end of Market Scan development
In August I could no longer look at this work as an experiment with models. Market Scan was finalized as a system where the research takes place without manually pressing each next button.
A year ago, it was simply impossible to replace a person with anything cognitive. Today it’s possible that it’s fucked up. I’ll show you the result of my fucking market scan very soon. It’s just being completed. Just when you think about the fact that not a single person there pressed a single button for this work - you’ll go crazy, unless of course you understand what bizdev, letters, research, etc. are on a professional level) A year ago if I said that I would replace people in this part of the business, that would be populism today this is real)
On the same day, the model roles diverged again. One wrote, another planned and checked direction, a third orchestrated complex tasks, and a fourth did the hands-on work. This was a production lineup, not a choice of one favorite model.
Easy. I now use Qwen only for copy because nothing else comes close to its writing. The working order is GPT Pro, then GPT 5.6 Medium or High, then Kimi.
Where PRO helps with a master plan and checks every 4 hours to see if we are moving there
GPT 5.6 medium for orchestrating simple tasks / high for complex ones
Kimi does the hands-on coding. I do not like it, but I have not found another configuration that works yet.
A week later, I double-checked the important assumption in a real run. The same model through subscription and API provided a different and sometimes unpredictable amount of reasoning. This means that it was not the name of the model that needed to be evaluated, but the specific mode in a specific circuit.
Speed matters most, but it is not the only factor. A CLI adds the weight of a large harness on top of everything already entering the model's context. That extra weight has to affect the result. When I used an API token, every quality metric for how the chatbot understood the doctrine behind the interview improved by 100% to 300%. Before that, I had tried to save money by testing only through subscriptions. Kimi exposed another problem: the subscription appeared to offer a reasoning control, but the setting had no reliable effect. Through the API, changing reasoning clearly changed the output and the metrics. Through the CLI subscription, Low, High, and Max often behaved the same. I assumed they were using every available load-management measure because an aggressively valued $18 billion startup was attracting demand from a market worth tens of trillions. One likely method was adaptive reasoning behind the subscription. You could select Max, but the load balancer decided what you actually received. In the API, the same simple, non-binding chat statement produced 105 reasoning tokens on Low and 2,450 on Max, roughly 25 to 30 times more. Through the subscription, the same request produced anything between 105 and 2,450 tokens, including both extremes. If Kimi seems to handle a request brilliantly, you are seeing it correctly. If it seems to handle the next one terribly, you are also correct. Both outcomes happen continually through the subscription, whether accessed through its CLI or subscription token. We tested the same behavior with both Kimi and Qwen.
By August 21, I had formulated the product to which all this was leading, and began in waves to remove old rails from the repository that could pull the system back again.
I launched each wave in a new task. When one task reported back, I sent its report to Pro for review, created the next task immediately, and asked the Ultra planner to take the next piece. Here is the exact prompt I used. I changed only the links to the ledger and the Pro chat where the repository review happened:
___
Dear Sol, hello! How are you Great things await you and me)
In essence, this is Self-Serve AI SDR, in which people purchase contacts or buy a market scan from us (through an interview and swipe with a card or crypto), after which we collect excellent Knowledge for them, on the basis of which we will create campaigns, attach the created boxes there on our platform, and start sending letters, allowing people to enjoy the fully automated process of all this from the moment they paid to the moment they started responding =) Although before there was always a lot of work that was not possible It’s clear who to entrust to do it properly.
So, in the process of moving towards this form, we had to go through a lot of changes and tests, and you can easily see these chronicles of development in the history of git changes.
The problem was that I lacked development experience and never asked anyone to manage the process properly. The repository accumulated a mountain of garbage: dead code and outdated functions that could drag us backward when a model found the wrong fragment and started building the new system on old rails.
Three days before the launch, what remained was not a new research architecture, but bringing the client part to a state in which the person who had not built the system all these months would not get lost in it.
Over the previous couple of months, I spent every last drop of my blood, plus the blood of everyone else in Notting Hill, to get my long-suffering project this far.
Before launch, I mainly had to finish the design of several client-facing systems. I got lost in the versions I had assembled quickly, which meant anyone who had not spent months building the system would have no chance at all.
We are now approaching the final stages of Market Scan development. I'm not trying to make another list generator anymore. I am bringing to the end a system that starts with the product, expands the market map itself, tests its own hypotheses, and only then moves on to companies, people, addresses and letters.
This system has left behind years of work with lists, dozens of manual parsing, expensive bases, unsuccessful architectures, hundreds of overgrown runners, thousands of lines of rules and constant runs of new models. Everything unnecessary gradually fell off. There is only one consistent path left from understanding the business to talking to the right person.
This is what I am finishing now.